


How to reduce alert fatigue without missing real incidents
Cut alert noise by tuning Prometheus rule timing, scoping maintenance silences, and routing actionable notifications to the right on-call team.
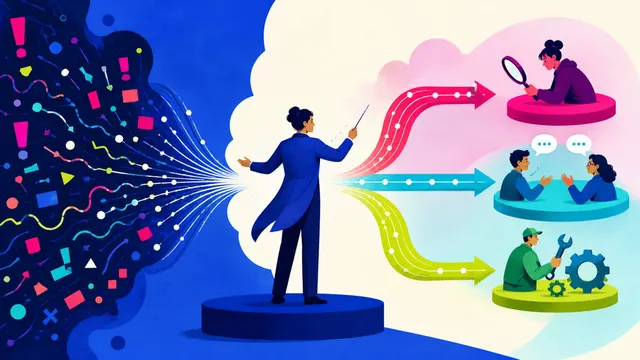
A checkout rollout sends three pages to the same engineer: CPU is high, a database connection pool is warming up, and the error rate has risen. The first two settle on their own. The third lasts long enough to threaten payments. Alert fatigue starts when all three demand the same response. Reduce it by deciding what warrants an interruption, what can wait, and what only needs a record.
Find out what the on-call engineer can do
Start with a recent incident and read the pages in the order they arrived. For each one, identify the affected service, the action it asked for, and whether anyone took that action. A brief spike with no user impact may be a false positive. A backup-start message is informational. Three alerts that ask for the same action may belong in one notification. A rule for a retired job may have no owner, and a valid warning can still be noisy if it pages at night when the work can wait.
Action rate is useful for spotting rules to review. A rare alert with serious consequences may see little activity in a 30-day sample. Check what it protects and whether another signal would catch the same failure before changing it.
Use timing where the service can tolerate it
A short spike in errors during a rollout may clear before a responder can do anything. Use the rule's timing to distinguish that spike from sustained impact. This Prometheus rule assumes an existing five-minute request error ratio, represented as a fraction between 0 and 1, with stable service and env labels. Tune the example threshold against traffic volume and the time you can afford to wait.
groups:
  - name: checkout
    interval: 1m
    rules:
      - alert: CheckoutHighErrorRatio
        expr: service:http_requests:errors_ratio5m{service="checkout", env="prod"} > 0.05
        for: 5m
        keep_firing_for: 2m
With one-minute evaluations, the same alert label set must keep matching for five minutes from its first matching evaluation before the alert fires. The five-minute measurement window and the for delay do different jobs. For an alert already firing, keep_firing_for keeps it firing for two minutes from the first evaluation where it no longer matches. That can absorb a brief dip or loss of data, and it also delays when the alert resolves. Use a separate rule for failures that need a faster response. Prometheus alerting rules
Mute the expected symptom during maintenance
When a rollout is known to trigger a warm-up alert, scope the silence to that alert, service, and environment. The example assumes your Alertmanager is reachable on localhost port 9093 and the warm-up alert has all three labels. It leaves unrelated rules and checkout error alerts eligible to notify.
amtool --alertmanager.url=http://127.0.0.1:9093 silence add \
  'alertname="CheckoutRolloutWarmup"' 'service="checkout"' 'env="prod"' \
  --duration=30m --author=oncall --comment="Checkout rollout warm-up"
In Guance, use Mute Management to select the affected monitor rules or tags. Filter further with event attributes, set the time range, and record the reason. Events are still generated during the mute. Incident notifications have a separate option where the selected scope supports it. After the window, verify delivery has resumed for matching events.
Group notifications and keep inhibition narrow
Alertmanager's group_by combines alerts with the same selected label values. Group by the dimensions a responder would handle together, such as alertname and cluster. The route controls the initial wait, when updates can be sent, and when unchanged notifications repeat. A group can still generate multiple notifications over its lifetime.
Inhibition suppresses notifications for target alerts while a matching source alert fires. For example, a known database outage can suppress dependent connection alerts for the same cluster if the rules match and the dependency is clear. Keep application error-rate alerts visible when they describe independent user impact. Make sure the labels used to tie the alerts together are present. Prometheus keeps evaluating its rules throughout. Alertmanager configuration
Guance Alert Policies also let you merge notifications or limit repeats. For rule-based and smart aggregation, check the configured window and what it groups before deciding which events should share a notification.
Route by ownership and urgency
A page should reach someone with both the access and the runbook to act. Route urgent production failures to the current on-call engineer. Send work that can wait to the owning team's queue. Decide who handles alerts without a team label, and test a representative alert through the routing tree. An on-call rotation spreads the load, and the escalation path should remain clear when a page goes unacknowledged.
Review whether the rule still earns a page
At each review, ask when the rule last fired, what the responder did, and where the runbook is. For a low-risk rule, you can move it to a quieter channel while you compare it with its replacement. Use an observation window that matches the failure frequency and impact. For a rare but critical failure, replay representative data or run a controlled drill to check that the rule still fires and routes correctly. Start new services with visible user symptoms and add resource alerts where they give someone time to prevent an outage.
Further reading · Configure Alertmanager routing and inhibition · Design an escalation policy
Contact us
Join the community

to join the community
Try Guance
Start online and pay only for what you use.
Get startedChoose a Guance plan