


What is incident management? A practical introduction
Understand how teams detect service incidents, coordinate response, restore service, and learn afterward. Covers alert triage, communication, tool selection, and MTTA/MTTR definitions.
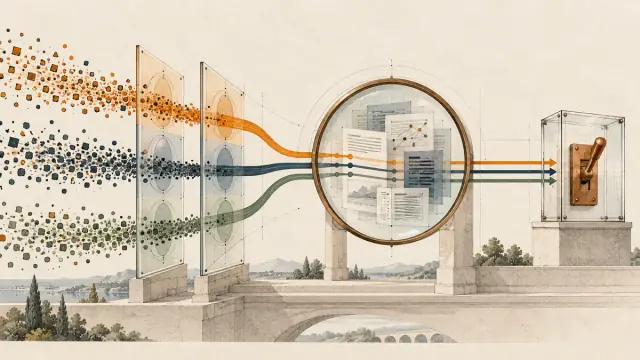
Several alerts can describe one outage, while a real service problem may first arrive as a support ticket. Incident management gives the team a way to turn those reports into coordinated work: establish the impact, assign responsibility, restore service, and keep people informed.
An incident is an unplanned interruption or reduction in service quality, from a rising API error rate to a service-wide outage. Managing it means organizing the response and restoring normal operation as quickly as practical. It does not require every contributing cause to be permanently eliminated before service can be considered restored.
Why incident management matters
Downtime can also damage the tools needed to recover. In its account of the October 4, 2021 outage, Facebook described losing connectivity between data centers worldwide. The outage also disrupted internal tools, making investigation and recovery harder.
Smaller services can face the same kinds of consequences, even at a different scale:
- Direct effects: lost revenue or customers.
- Indirect effects: damaged trust, greater pressure on the team, and declining morale.
A maintained response process can reduce those effects. It gives detection and recovery a clear owner, helps responders work together, and keeps customers and other stakeholders informed. The review afterward turns what the team learned into changes it can track.
Four common parts of the response
The following four activities are a useful way to explain the work, rather than a universal industry-standard sequence. They can overlap and repeat as the incident develops. Teams choose their own severity levels, roles, and escalation rules.
1. Detect and assess the incident
Give reports a clear entry point. Synthetic availability checks, metric monitors, and APM alerts produce signals under configured rules; support teams and engineers can report problems manually. Assess impact, urgency, and related signals before creating or linking an incident record.
A single source of truth means responders can find the same current status, owner, and timeline. That record can link several tools. It does not require every alert to live in one physical system, or every alert to page a person.
In Guance, configure the relevant monitor and alert policy, then use the Event Center to inspect the events that were generated. Event generation, incident creation, and notification are separate parts of the path. Check the detection rule and incident association or aggregation settings. Monitor notifications also depend on alert policies and muting settings, while incident notifications use their own configured on-call and escalation rules, recipients, and channels. Seeing an event does not establish that a responder received a notification. The Event Center itself aggregates and queries events; it does not send notifications.
2. Communicate with stakeholders
Once the impact and response priority are understood, arrange internal and external communication accordingly. Major or user-visible incidents particularly need a clear update cadence.
- Internally: bring responders together and assign responsibilities. A major or cross-team incident benefits from an Incident Commander; a small incident may have one person covering several roles.
- Externally: update the status page and support messaging as appropriate to the impact. State what is known and when the next update will arrive. Do not present an unverified causal theory as a confirmed explanation.
3. Restore service
The on-call responder leads the initial investigation and brings in additional expertise through an escalation policy when needed. Restoration comes first: a rollback, traffic shift, or temporary reduction in functionality may reduce impact before the full explanation is available.
Keep the investigation and longer-term work visible after recovery. Restoring service and permanently removing all contributing causes are different milestones.
4. Review what happened
Use agreed impact and recurrence criteria to decide the depth of review. A postmortem records the timeline, confirmed causes and contributing factors, impact, and follow-up actions. Give those actions owners and due dates so the review produces maintained work.
A blameless review examines the conditions, system design, and processes behind decisions, rather than stopping at an individual's mistake. That makes it easier to share what was known at the time. In root cause analysis, distinguish evidence from hypotheses. Complex incidents can have several contributing factors; forcing them into one “root cause” can hide work that still needs doing.
Choose tools around the response work
Look for capabilities the team can use together:
- Alert intake and on-call scheduling: bring signals from multiple monitoring sources into a manageable workflow and maintain coverage as rotations change.
- Notification and escalation: verify supported phone, SMS, and messaging channels, delivery information, acknowledgement behavior, and the conditions for escalation.
- Collaboration: keep the incident timeline and task assignments accessible to responders.
- Status communication: provide a way to publish updates for affected stakeholders.
- Review and measurement: track follow-up work and calculate response metrics using consistent definitions.
Define those metrics before comparing dashboards. For example, MTTA can mean the average time from an alert being raised to human acknowledgement. A service-restoration duration can run from the start of impact to restoration. MTTR may refer to repair, recovery, resolution, or response in different teams. Specify the start and end timestamps, included population, and treatment of still-open incidents. Averages from different definitions are not directly comparable.
Common questions
How does incident management differ from problem management?
In IT service management, incident management focuses on restoring service. Problem management identifies and manages causes, known errors, and workarounds to reduce the likelihood and impact of recurrence. It does not promise that every cause can immediately be eradicated. Switching to a standby database to restore service is incident response; investigating the contributing conditions and tracking a permanent fix or reliable workaround is problem-management work.
Does a small team need a formal process?
Yes, but it can be lightweight. Start with an on-call rotation, a clear place to collect and track reports, and a review template. A small team still needs to know who responds and where to find the current state when an alert arrives overnight.
Should every alert become an incident?
No. Distinguish monitoring signals, service incidents that need tracking, and problems that require an immediate page. Duplicate or informational alerts can be grouped, suppressed, or retained as records. An incident that already affects service can still need recording, classification, and scheduled work even if it is not urgent. Decide incident creation and notification separately, using impact, urgency, and configured rules.
References
- Google SRE: managing incidents
- Google SRE: blameless postmortems
- Atlassian: problem management
- Atlassian: incident response metrics
- Guance monitor rules
- Guance alert policies
Technical references checked November 5, 2026.
Contact us
Join the community

to join the community
Try Guance
Start online and pay only for what you use.
Get startedChoose a Guance plan